OPERA: A Unified Omnimodal Progressive Spatio-Temporal Reasoning Agent for Referring Video Segmentation
Overview
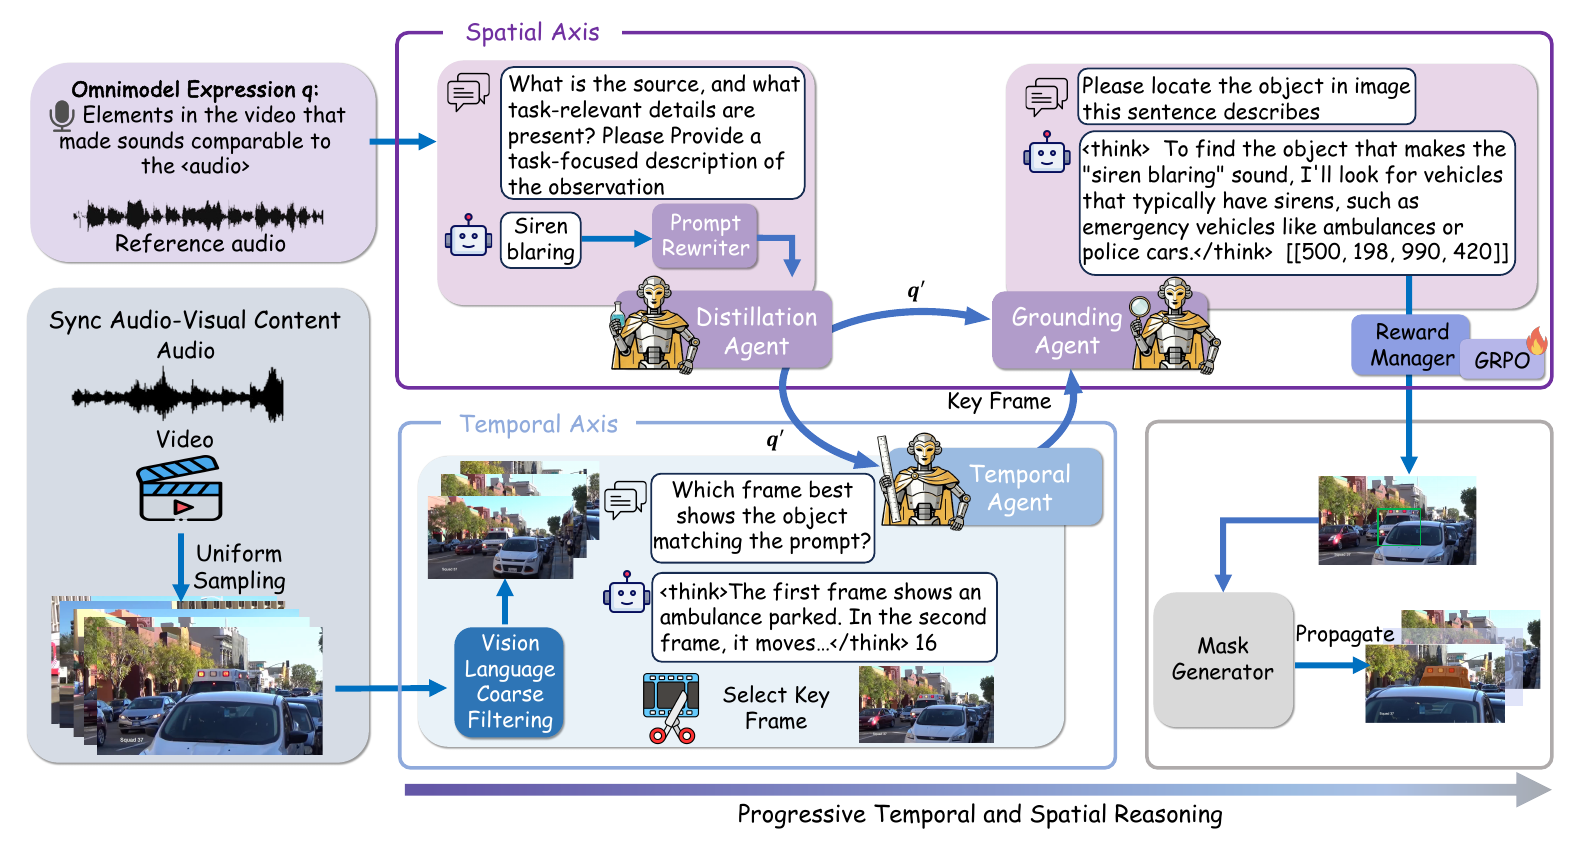
We propose OPERA, a referring video segmentation agent that uses one multimodal large language model to interpret text, audio, and reference-image queries. It progressively selects an informative video frame, distills the query into a target description, and localizes the target with GRPO-enhanced grounding. Mask propagation then extends the segmentation across the video. OPERA achieves state-of-the-art results on OmniAVS and Ref-AVS, with zero-shot transfer to standard referring video segmentation benchmarks.